From VLAs to WAMs: what changed by August 2026
WoRV / MaumAI
2026-08-31
01
Robot Foundation Models Today
The VLA recipe, and where it strains
Bigger backbones, more teleop hours, broader embodiments: the axis of progress stayed the same.
Teleoperation rigs and handheld grippers feed every VLA. The strain: an hour of robot time buys one hour of one embodiment’s data.
02
World Models
Learning the environment itself
| Family | Exemplars | What it gives you |
|---|---|---|
| Latent dynamics | Dreamer | imagination for planning and RL |
| Video generation | Genie, Cosmos | promptable, general visual worlds |
| Neural simulators | DreamDojo, GE-Sim | action-conditioned rollouts for robots |
Announced at NVIDIA GTC Taipei, May 31, 2026; rankings per NVIDIA’s launch announcement.
| Who | May to Jul 2026 | The move |
|---|---|---|
| Google DeepMind | Project Genie + Street View | Street View imagery grounds interactive worlds |
| World Labs | SceniX, real to sim to real | scanned scenes into policy-training simulation |
| GE-Sim 2.0 | one world model, three jobs | scores rollouts, yields rewards, accelerates them |
| DreamZero | DreamDojo | |
|---|---|---|
| Direction | joint: video + action | forward: action to video |
| The product | a zero-shot policy | a neural simulator |
| Training data | 500 h of robot data | 44,000 h of human video |
| Its job | acts | imagines |
Both were released by NVIDIA in February 2026: two halves of one loop.
03
World-Action Models
One model that imagines and acts
| Style | Idea | Exemplar |
|---|---|---|
| Joint denoising | one flow over video and action | DreamZero |
| Interleaved mixture | mixture-of-transformers over frames and actions | Dyna-2 |
| Latent world + decoder | imagine in latent space, decode actions | LAPA lineage |
Representation-only Fast-WAM skips video generation at inference and delivers VLA-class latency at about 190 ms.
Named customer: Din Tai Fung. The fleet collects about 1 TB per day.
| Who | Scale | What |
|---|---|---|
| Dyna Robotics | 1,000,000 h | egocentric human video, no robot data in pretraining |
| Generalist AI | 500,000+ h | manipulation data, about 9,000 end-effectors |
| Lightwheel EgoSuite | 100,000 h, open | egocentric video, commercial training allowed |
| Amazon ABC-130K | 3,553 h, open | 134,806 bimanual teleop episodes |
| China | 90+ data factories | operating or under construction |
China: Interact Analysis, Aug 2026. Curse of Precision, Jul 2026: data needs grow super-exponentially near the system limit.
1M
What does a million hours buy?
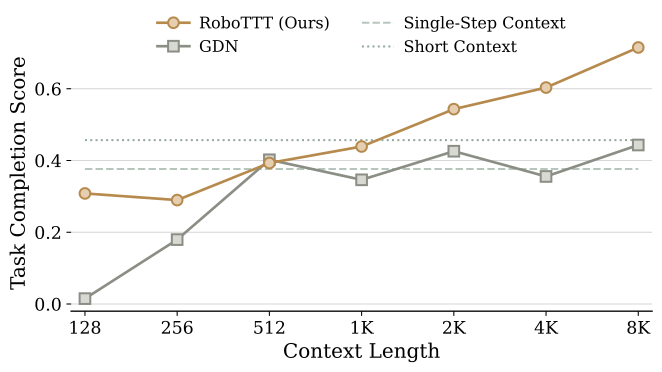
Six weeks in summer 2026: the in-context learning wave
| Date | Who | Claim |
|---|---|---|
| Jul 16 | RoboTTT, NVIDIA | context length as a new scaling axis; one-shot 6/10 from a human video |
| Aug 18 | Skild S1 | one human video runs an unseen 10-minute task; 66% vs 9% |
| Aug 19 | GEN-1.5, Generalist AI | physical prompting: one-shot 59%, no gradient updates |
| Aug 26 | Zero-WAM, Robbyant | in-context WAM: +29.5 pp over the best baseline |
Figure: NVIDIA GEAR, RoboTTT, arXiv:2607.15275.
04
So What Changed?
VLA, world model, WAM, side by side
| Architecture | Scales on | Actions come from | August 2026 signal |
|---|---|---|---|
| VLA | teleop demos | imitation head | π0.5: RoboArena Elo 1609 |
| VLA + WM | demos + video | imitation, WM-guided | π0.7 visual subgoals |
| World model | video | none: it imagines | real-time neural simulators |
| WAM | egocentric video | joint or video-conditioned action pathway | DreamZero: Elo 1736 |
| Hybrid | everything | both pathways | the predicted winner |
NVIDIA, Jun 2026: action tuning uses 9 ZFLOPs; full video pretraining uses 50+ ZFLOPs; generative WAM inference takes 3 to 4 times as long as π0.5.
| VLA | World model | WAM | |
|---|---|---|---|
| Learns | behavior | dynamics | dynamics + action coupling |
| Scales on | teleop hours | video | video priors + robot trajectories |
| The 2026 turn | absorbing world models | converging on robot training | one-shot via in-context learning |
Thank you. Questions welcome: sung@maum.ai
Appendix
Backup detail for Q&A
| Thread | Evidence |
|---|---|
| HumanGen dataset | 74.2K human-robot pairs across 8.6K tasks |
| RoboTwin 2.0 held-out suite | 47.0%, +29.5 pp over LingBot-VA |
| BPP, Stanford | task diversity, not hours, drives ICL ability |
| MimicDroid, UT Austin | the earlier academic thread, ICRA 2026 |
| Source | The fine print |
|---|---|
| EgoSuite-Open100K | 90k head-view + 10k wrist hours, LeRobot format |
| ABC-130K | 3,553 h, 134,806 episodes, bimanual YAM, fully open |
| UBTECH | 566M CNY of humanoid orders across three cities, 2025 |
| Curse of Precision | \log N \propto 1/(P-c): required demos grow super-exponentially as precision P nears limit c |
| Topic | Where |
|---|---|
| DreamZero and DreamDojo | 2602.15922, 2602.06949 |
| WAM tutorial, survey, Fast-WAM | 2607.00836, 2606.00113, 2603.16666 |
| Cosmos 3; Rise of World-Action Models | 2606.02800; NVIDIA blog, Jun 2026 |
| RoboTTT, Zero-WAM, BPP | 2607.15275, 2608.26103, 2606.30457 |