Lecture sources
Action as a New Modality and the Scaling of Robot Learning Data Yunsung Lee · DGIST HSS118 · October 2, 2026
Open the slides · Course schedule
References linked from the lecture slides. Figures and video excerpts are credited on the corresponding slides.
Introduction
1. What did language models learn from?
- Jason Wei, Stanford CS25 (2024), slide 4
- Wei, Stanford CS25 (2024), slide 6
- Wei, Stanford CS25 (2024), slide 7
- Wei's chalkboard explanation
- Jason Wei, Stanford CS25 (2024), slide 13
2. Learning to act
- ETH Robot Learning (2026)
- Qwen2.5-VL (2025)
- Qwen2.5-Omni (2025)
- MIT Robotic Manipulation, Fall 2025, Lecture 20, p2
- Levine, Berkeley CS285, Spring 2026, p12
- Stanford CS231n (2025), p29
- OpenVLA (2024)
- Mees, ETH Robot Learning (2026), 52:30-54:20
- Stanford CS224R, Introduction (2025)
3. Collecting experience
- Zhao et al., ALOHA (2023)
- ALOHA 2 (2024)
- UMI (2024), section VII
- Chi et al., UMI (2024), Fig2 and project demo
- Sunday Robotics (2025)
4. Scaling with human video
- Sergi Coffee (YouTube)
- CC BY 4.0
- Punamiya et al., EgoVerse (2026), capture setup
- EgoVerse annotation demo (2026)
- EgoSuite-Open100K announcement
- Generalist GEN-1.5 demos (2026)
- GEN-1, Apr 2
- Dyna-2 (2026), Figure 4
5. Learning from more kinds of video
- Proske & Gandevia (2012)
- Ego4D
- V-JEPA 2 (2025)
- AFC, Australia v Korea Republic (2024)
- D’Innocenzo et al. (2016)
- Original diagram
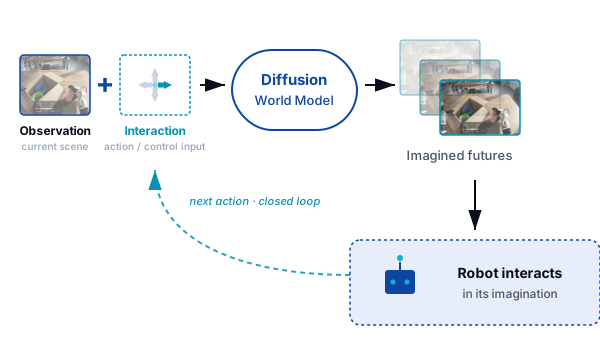
- DreamDojo
- Genie 3
- V-JEPA
- LeWorldModel
- CMU (2025), p35
- V-JEPA 2
- DreamDojo
- LeWorldModel